I work on audio, language models, and learning from human preference. My research includes reward modeling and post-training for AI agents, personalized generation, and models of speech and conversation.
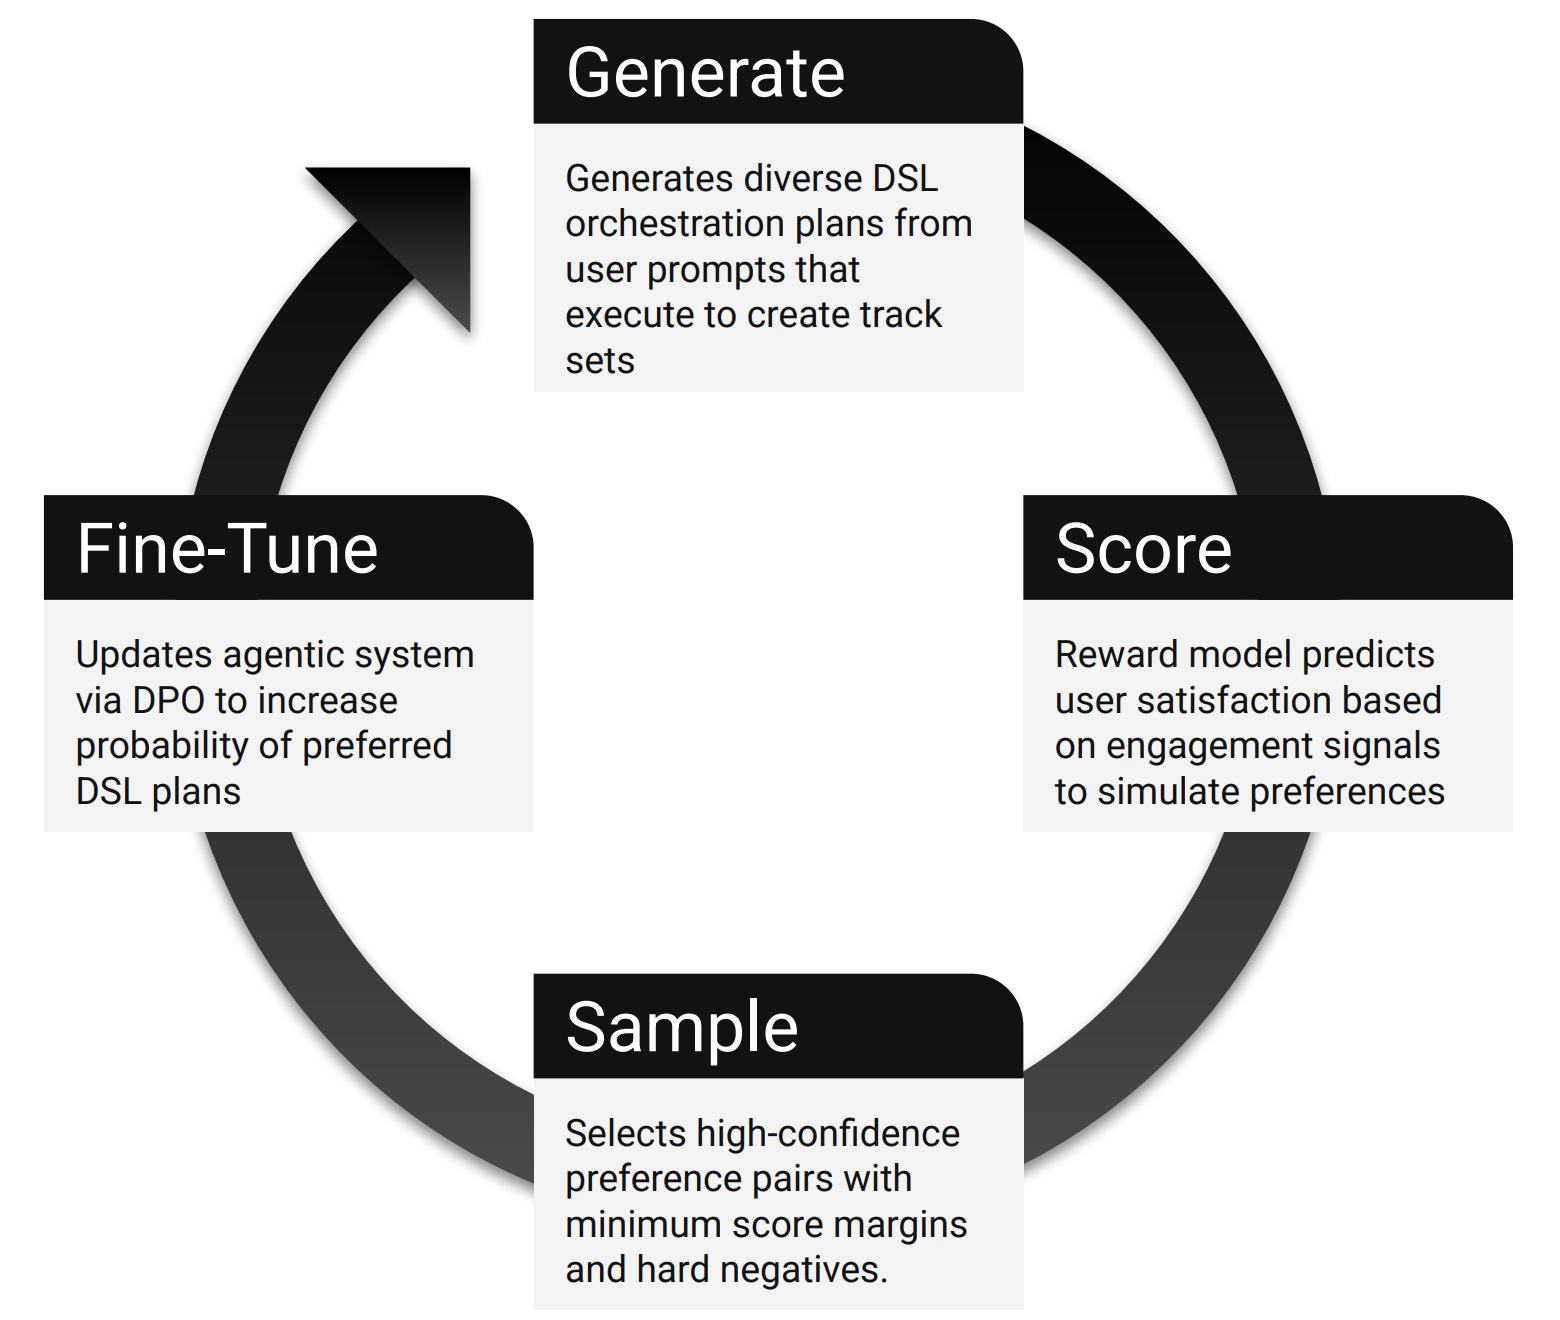
At Spotify, I combined reward modeling with direct preference optimization (DPO) to train music agents from listening feedback. The approach improves tool-use plans using feedback on the playlists they produce. Production A/B tests showed 70% fewer erroneous tool calls and 4% more listening time.
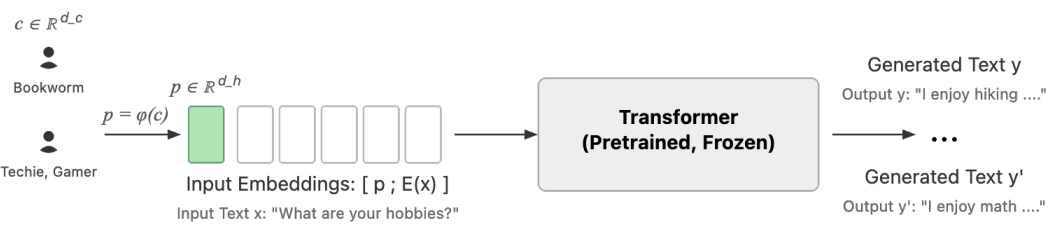
Embedding-to-Prefix (E2P) maps existing user embeddings to a single learned soft prefix token, personalizing a frozen LLM without updating its weights. I developed the method at Spotify; it was used for long-term personalization in GLIDE, a generative podcast recommender.
Personalization through a learned prefix; the language model stays frozen.
Models of conversational speech
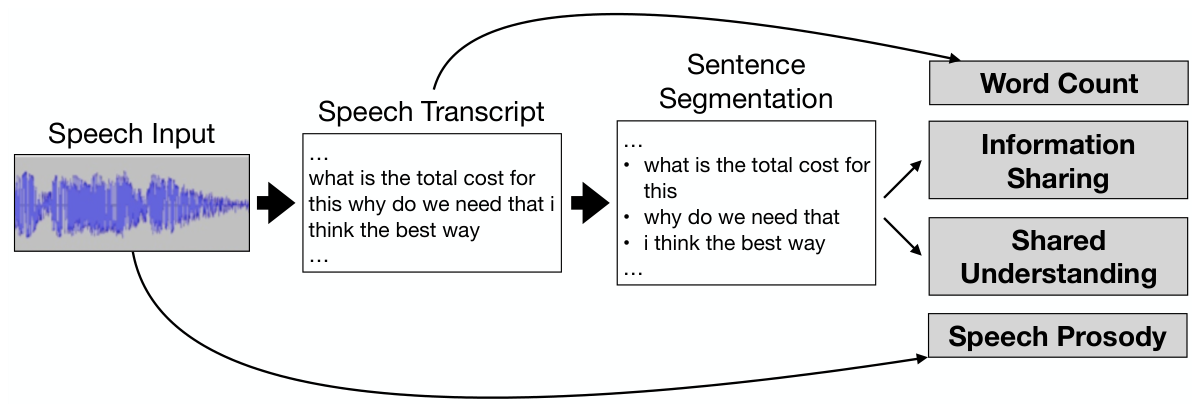
I developed SpecialTime and Meeter to analyze spoken conversation. SpecialTime provides real-time feedback on dialogue acts in parent–child speech. Meeter uses transcription, sentence segmentation, and classification to measure information sharing and shared understanding in group discussions. My speech research also includes real-time emotion recognition on mobile devices.
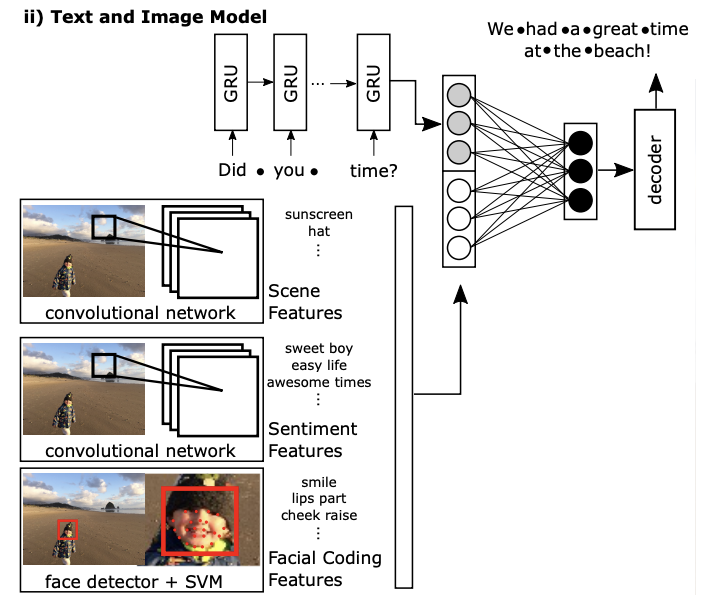
With Microsoft Research, I developed dialogue models conditioned on visual sentiment, scene features, and facial expressions. Compared with text-only models, image grounding produced more informative, emotional, and specific replies.